Jira Issues management

An event-driven backend project

A backend that loses no events
and does no work twice.

A distributed issue tracker, built as microservices that talk to each other through events. Writes are idempotent, events stay durable even when something fails, and every piece scales on its own. Here are the architecture decisions and, above all, why they were made this way.

Local development

How an event flows through the system The client creates an issue in issue-service, which stores it alongside an event in PostgreSQL within the same transaction; the relay reads the event and publishes it to a Redis Stream, which notification-service consumes. POST same tx SKIP LOCKED XADD XREADGROUP Client HTTP issue-service Express · TS idempotency + tx PostgreSQL issues outbox relay daemon Redis Stream events notification-service idempotent consume Redis idempotency · idem:*

AWS production

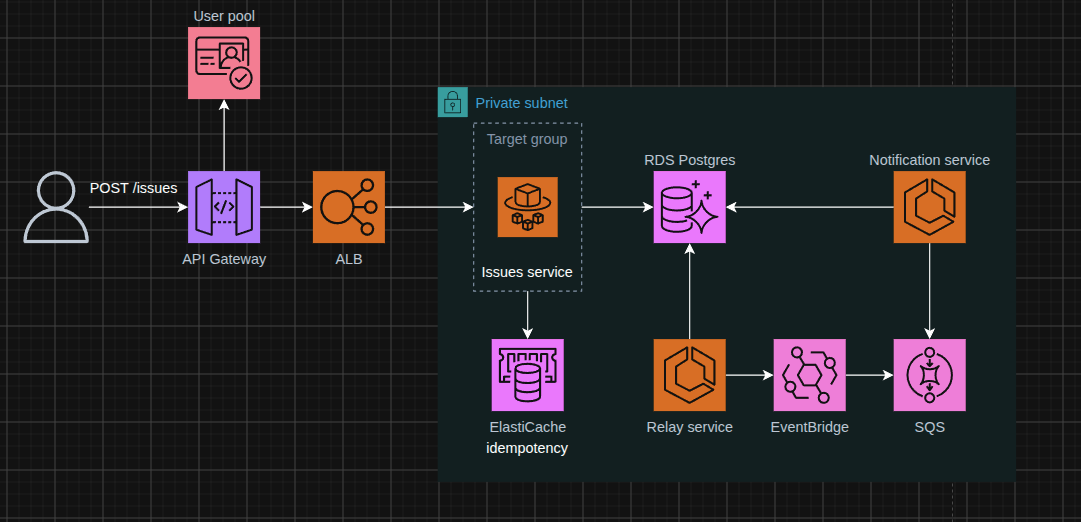
How an event flows through the system The client creates an issue in issue-service, which stores it alongside an event in PostgreSQL within the same transaction; the relay reads the event and publishes it to a Redis Stream, which notification-service consumes. POST same tx SKIP LOCKED PutEvent Client HTTP issue-service Express · TS idempotency + tx RDS issues DB outbox relay daemon AWS EventBridge events AWS SQS with DLQ notification-service idempotent consume ElastiCache idempotency · idem:* RDS notification DB
The event travels from the issue being created all the way to the consumer, without getting lost.

Infrastructure Architecture Diagram

What a senior job post asks for, solved

RequirementHow it is solved
idempotency An Idempotency-Key header + Redis (SET NX EX) on writes; deduplication by event_id on consumption.
event-driven Transactional outbox + relay + Redis Stream locally, or SQS/EventBridge on AWS, behind a replaceable port.
resilient Outbox (no lost events), retries, FOR UPDATE SKIP LOCKED, a DLQ, health/readiness, and graceful shutdown.
scalable API, relay, and consumer are independent processes that scale separately; consumer groups; ECS auto-scaling.
secure Least-privilege IAM per service; CI/CD with OIDC (no static keys); managed secrets.
rate limiting API Gateway throttling and usage plans enforce per-client request limits and burst control.

How an event flows

The style runs throughout: layers (controller → service → repository) with dependency injection and ports/adapters for anything that crosses the boundary (database, broker). The domain depends on interfaces, not technologies, so switching broker or database is writing a new adapter.

  1. 1

    The client sends POST /issues with an Idempotency-Key.

  2. 2

    The middleware reserves the key in Redis with SET NX EX; a retry does not create the issue twice.

  3. 3

    The service opens a transaction with a Unit of Work.

  4. 4

    In the same transaction it writes to issues and outbox: either both are saved, or neither.

  5. 5

    The relay reads the unpublished events with FOR UPDATE SKIP LOCKED.

  6. 6

    On local machine, it publishes them to the Redis Stream through the EventPublisher port. On AWS production, it publish them to EventBridge and then to SQS.

  7. 7

    notification-service consumes them idempotently, with a DLQ and its own database.

API reference

The REST surface of issue-service. Requests and responses are JSON. The base URL is shown below; every path is relative to it.

base https://kas8ywotfi.execute-api.us-east-2.amazonaws.com/v1

POST /issues

Creates an issue. Supports idempotency through the Idempotency-Key header: a retry with the same key returns the already-computed response instead of creating the issue twice.

Request headers

HeaderValue
Content-Typeapplication/json
Acceptapplication/json
Idempotency-KeyA client-generated key to make the write idempotent on retries.

Request body

FieldTypeDescription
titlestringShort summary of the issue. Required.
descriptionstringDetail of what happens. Required.
{
  "title": "Cart button bug",
  "description": "Button makes no actions"
}

Response · 201 Created

{
  "data": {
    "id": "b1e3c7a2-4f8d-4c1a-9e2b-0a6d5f3c1e90",
    "title": "Cart button bug",
    "description": "Button makes no actions",
    "status": "open",
    "createdAt": "2026-09-10T14:22:05.123Z",
    "updatedAt": "2026-09-10T14:22:05.123Z"
  }
}
GET /issues

Returns the list of reported issues. issue-service is the source of truth for the issues table.

Request headers

HeaderValue
Acceptapplication/json

Response · 200 OK

An object with a data array of Issue.

{
  "data": [
    {
      "id": "b1e3c7a2-4f8d-4c1a-9e2b-0a6d5f3c1e90",
      "title": "Cart button bug",
      "description": "Button makes no actions",
      "status": "open",
      "createdAt": "2026-09-10T14:22:05.123Z",
      "updatedAt": "2026-09-10T14:22:05.123Z"
    }
  ]
}

Decisions and their reasoning

idempotency

Idempotency on writes

Problem
A client that retries a POST after a timeout must not create the issue twice.
Decision
A middleware using SET key value NX EX ttl in Redis (ElasticCache on production); the first request wins and stores the response, duplicates get the already-computed response.
Why
Redis is coordination and deduplication, not the source of truth. Only 2xx responses are cached, and the lock has a short TTL so it does not stay locked if the process dies.
throttling

Rate limiting

Problem
Public REST endpoints can be abused with high-frequency requests, enabling brute-force attacks and exhausting backend capacity.
Decision
Enforce rate limiting at API Gateway using route-level throttling and usage plans, with per-client request quotas and burst limits.
Why
Blocking abusive traffic at the edge reduces attack surface, protects downstream services, and keeps legitimate users responsive during spikes or malicious scans.
postgres

PostgreSQL without an ORM

Problem
Fine-grained control over queries and transactions is needed, without layers of indirection.
Decision
Direct access with pg and hand-written SQL, behind repositories with their interface.
Why
Transactions (the basis of the outbox), partial indexes, and FOR UPDATE SKIP LOCKED are used as-is; the cost of writing SQL by hand is acceptable.
migrations

Custom migrations, no ORM or library

Problem
The schema must be versioned and applied safely, and Docker's init step does not exist on RDS.
Decision
A custom runner over pg with a schema_migrations table, run as a step before the deploy.
Why
pg_advisory_lock means only one replica migrates at a time; checksums detect drift; one transaction per migration. Robust with several ECS tasks during a deploy.
outbox

Transactional outbox

Problem
Writing the issue and publishing the event separately can fail halfway: a lost event or a phantom event (dual-write).
Decision
The event is inserted into outbox within the same transaction as the issue, via a Unit of Work that shares the connection.
Why
The business fact and its event are committed together or not at all. It is the foundation of the system's reliability.
relay

Relay: a separate, always-on process

Problem
Something has to move events from the outbox to the broker without coupling that latency to the API.
Decision
A separate daemon reads the unpublished rows with FOR UPDATE SKIP LOCKED and publishes them; it sets published_at.
Why
Several instances can run in parallel without stepping on each other; if the relay goes down, events pile up and drain when it returns. Nothing is lost.
broker

Redis Streams or EventBridge/SQS, not Kafka or RabbitMQ

Problem
Reliable consumption is needed (groups, ACK, retries) without carrying the operational weight of a dedicated broker.
Decision
Redis Streams locally (a persistent log with consumer groups and XACK), behind the EventPublisher port.
Why
It was already in the stack and the volume does not justify Kafka/RabbitMQ. The broker is a replaceable detail: on AWS it is swapped for SQS/EventBridge without touching the domain.
consumer

Idempotent consumer with a DLQ

Problem
Delivery is at-least-once: an event may arrive duplicated, and a message that always fails must not block the group.
Decision
Deduplicate by event_id with ON CONFLICT DO NOTHING in the same transaction as the effect; reclaim pending messages with XAUTOCLAIM and send to a DLQ once the delivery threshold is exceeded.
Why
Duplicates do not repeat the effect; permanent errors go to the DLQ and transient ones are retried. The group never gets stuck.
ownership

Each service owns its data

Problem
Sharing tables between services creates a coupled distributed monolith.
Decision
notification-service has its own database; services communicate only through events.
Why
It lets each service evolve and deploy independently. It is what makes this real microservices.

From local to AWS

Every local piece has its managed equivalent. Designing with ports makes the jump mostly a matter of swapping adapters and configuration.

LocallyOn AWS
redisElastiCache
postgresRDS
redis streamSQS / EventBridge (the port's production adapter)
processesECS Fargate: API, relay, and consumer as services that scale and fail separately
edgeAPI Gateway → internal ALB (throttling, authorizer, usage plans)
migrationsA pre-deploy task (same image, command migrate up)
ci/cdGitHub Actions + OIDC (no static keys) → ECR → ECS; least-privilege IAM

CI/CD: OIDC to AWS, no static keys

On merge to main, GitHub Actions runs the tests, authenticates to AWS through OIDC — with no long-lived credentials — and builds, tags and pushes the Docker images to ECR. GitHub issues a short-lived JWT on every run; AWS trusts the issuer through an OIDC provider and a least-privilege IAM role whose trust policy pins the token's sub. There is nothing to store, rotate, or leak. This pipeline covers build + push; the ECS deploy is a later step, not included yet.

AWS / GitHub pieceRole in the pipeline
OIDC provider token.actions.githubusercontent.com, audience sts.amazonaws.com.
IAM role Your role: trust policy scoped to this repository; least privilege — only ecr:GetAuthorizationToken (account level, required) plus the push actions (PutImage, InitiateLayerUpload, …) bound to the two ECR repository ARNs. No AdministratorAccess, no Resource: "*" beyond what AWS mandates.
GitHub secret Only AWS_ACCOUNT_ID, kept in the production Environment; region and ARNs are interpolated in the YAML.

Pipeline on push to main

  1. 1

    dorny/paths-filter computes which service folders changed; each build job skips if its service was untouched.

  2. 2

    Tests run as a gate: pnpm typecheck && pnpm test before building anything.

  3. 3

    The job declares environment: production and calls configure-aws-credentials, which requests temporary credentials via sts:AssumeRoleWithWebIdentity.

  4. 4

    amazon-ecr-login authenticates the Docker client against ECR.

  5. 5

    docker build --platform linux/amd64, then push with two tags: $GITHUB_SHA (immutable, used in deploys) and latest (dev convenience only).

The claim that cost the most time: sub

GitHub identifies each run with a sub claim inside the OIDC token, and its format is not the one in the generic docs. For repos created after 15 Jul 2026 (like this one) the sub carries immutable numeric IDs, and declaring an environment: rewrites it again. A trust policy written for the old format simply never matches, and AWS rejects the assume with a generic authorization error.

# Old repos
repo:OWNER/REPO:ref:refs/heads/BRANCH

# Repos created after 15 Jul 2026 (immutable owner/repo IDs)
repo:OWNER@OWNER_ID/REPO@REPO_ID:ref:refs/heads/BRANCH

# Any job that declares environment: (branch drops out)
repo:OWNER@OWNER_ID/REPO@REPO_ID:environment:production
environment

environment: rewrites the sub and moves the branch guard

Problem
A job needs environment: production to read that Environment's secrets, but this drops the branch from the sub, so the role condition can no longer pin a branch.
Decision
The role condition matches the environment:production form of the sub; the branch guard moves to Settings → Environments → production → Deployment branches in GitHub, where the production Environment is protected to allow only the main branch. As a result, the pipeline runs only when code is merged to main.
Why
GitHub blocks the job before it even requests the token if the run is not on main, so a build never even reaches AWS from any other branch. Keep in mind: the branch guard for this role now depends entirely on that Environment rule.
sts:TagSession

Session tagging permission

Problem
configure-aws-credentials@v4 tags the session with run metadata by default, which needs sts:TagSession in the trust policy; without it the assume fails with the same generic error.
Decision
Disable tagging — it is not needed here — with role-skip-session-tagging: true.
Why
It keeps the trust policy to just sts:AssumeRoleWithWebIdentity and removes one silent cause of authorization failures.

Project status